Suchir
Flagship framework
Beetle
Small models. Big questions.
An open-source framework I built for controlled bilingual & multilingual language-model pretraining and interpretability — now released.
Now open source
Beetle is released
The software is live. Everything below points you to it.
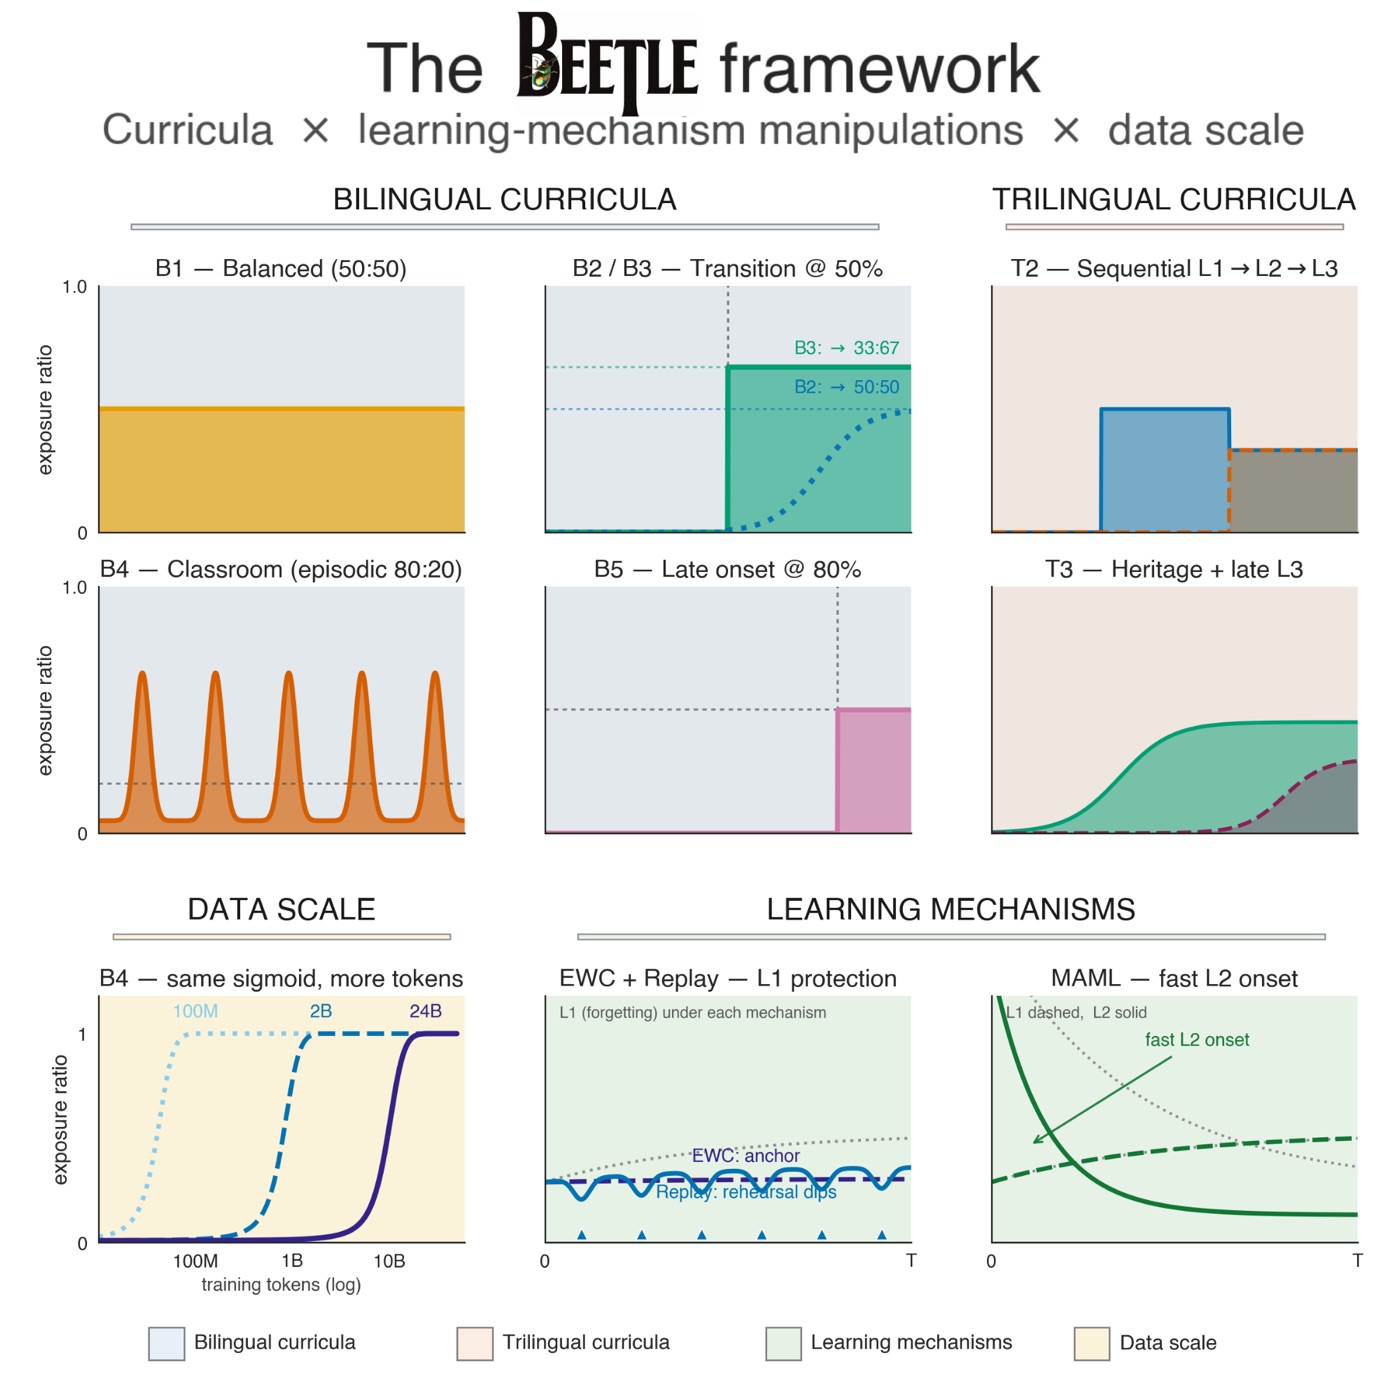
Beetle is a framework I designed and built for controlled bilingual and multilingual pretraining. It gives you a single, declarative interface in which the tokeniser, the target language, the training budget, and the exposure structure of the data can each be manipulated independently, all configured through YAML. It grew out of computational psycholinguistics, but it is a general interpretability and controlled-pretraining infrastructure: because every model is checkpointed densely and exposure is a first-class variable, you can ask when and how abilities emerge, not just whether a final model has them. I designed the system, trained the models, and authored the libraries; it builds on the PicoDecoder backbone from PicoLM.