PhD Candidate · University of Cambridge

Suchir Salhan

I study how AI systems learn — treating small, human-scale language models as scientific instruments.

PhD candidate in Computer Science at the University of Cambridge (Gonville & Caius College), working across machine learning, cognitive science and linguistics to understand how language models acquire capabilities and develop internal representations during training.

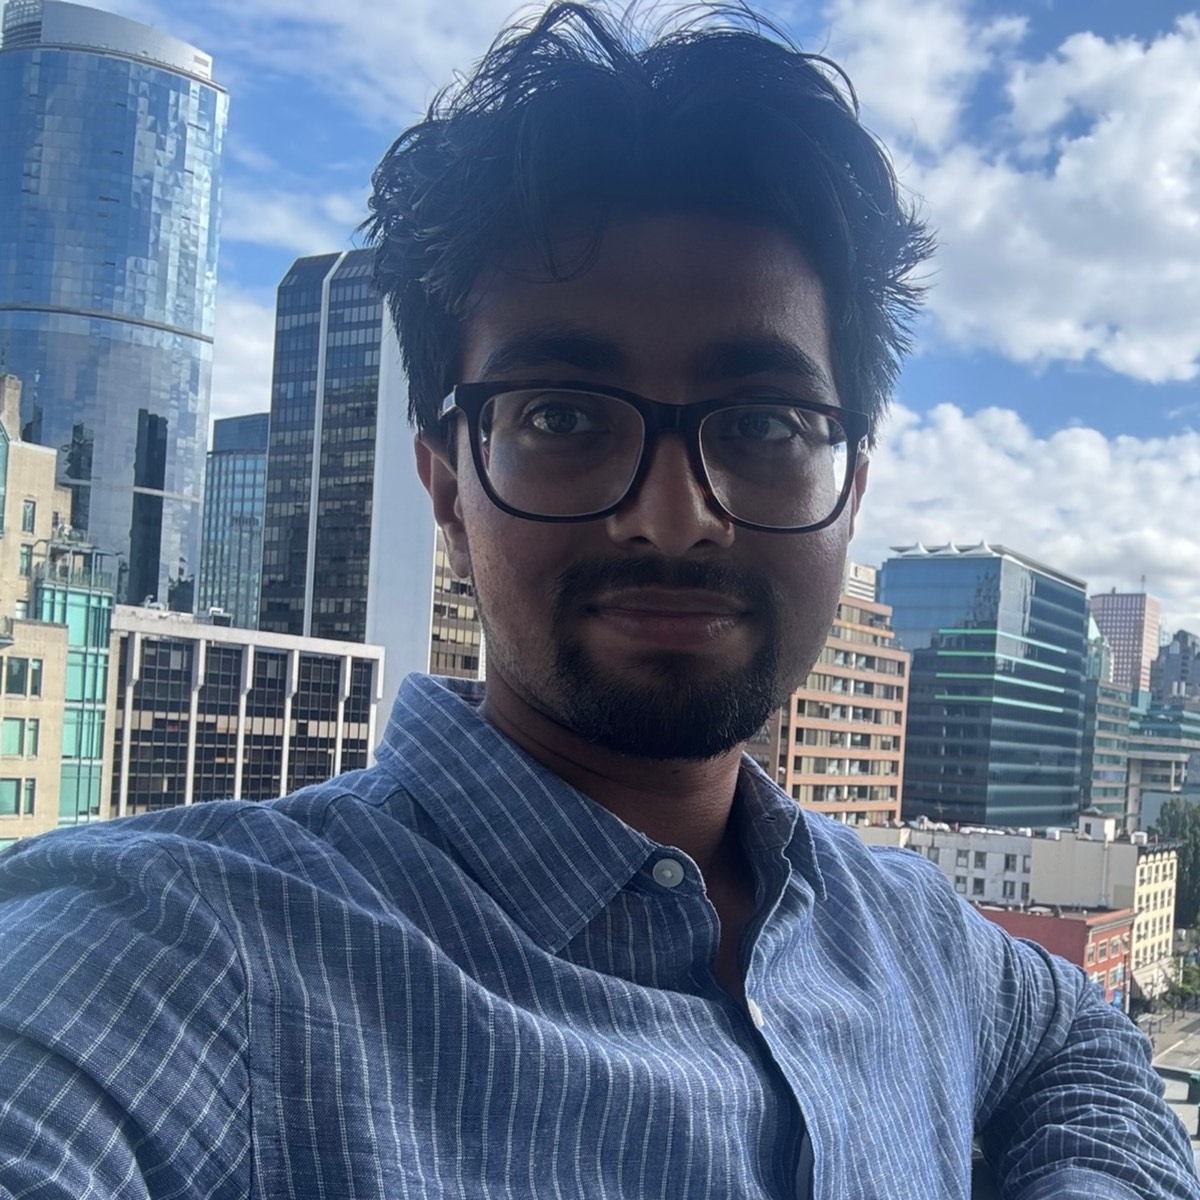
Portrait of Suchir Salhan
25+
Peer-reviewed publications, with first-author work at EMNLP & EACL
2
Outstanding Paper Awards, BabyLM Workshop (EMNLP 2025)
330
Open small language models in the Beetle suite
2
Research challenges co-organised: BabyLM & BabyVLM

Research at a glance

How do intelligent systems learn?

I study learning as it unfolds through training. Rather than only measuring what a finished model can do, I use small, human-scale language models as controlled experiments — tractable enough to inspect directly, yet rich enough to test hypotheses drawn from human language acquisition and cognition. Four connected questions run through the work.

Developmental interpretability

How do capabilities and internal representations emerge during training — and can we monitor that development before standard evaluations detect it? This connects interpretability to AI safety.

Learning dynamics & interpretability

Sample-efficient, human-scale learning

Humans learn language from far less data than today's models. Which architectures and training strategies let a model acquire real capabilities from child-sized data budgets? This drives the BabyLM and BabyVLM challenges.

Human-scale modelling

Multilingual & bilingual learning

Most people use more than one language, yet models of language processing are largely monolingual. By controlling what languages a model sees, and when, I test how linguistic experience shapes what it learns and generalises.

Beetle model suite

Tokenization & adaptive computation

Tokenization is usually a fixed preprocessing step. I treat it as a learned resource-allocation policy: can a model decide how much computation to spend on different parts of its input?

Efficient architectures

Selected projects

Open research infrastructure

Two open-source projects anchor my research programme — one a suite of controlled models, the other the framework that trains and studies them.

Learning-dynamics curves from the Beetle bilingual model suite

Beetle · Bilingual model suite

Beetle

The problem. Computational models of human language processing have focused heavily on monolingual speakers, even though most people in the world use more than one language.

What I build. Beetle is a framework and a collection of 330 small language models trained under controlled bilingual and monolingual settings — matched populations that differ in a specific aspect of their learning history.

Why it matters. This experimental control lets us test hypotheses about bilingualism — code-switching, language attrition, heritage learning — that are difficult to study in larger, less transparent systems.

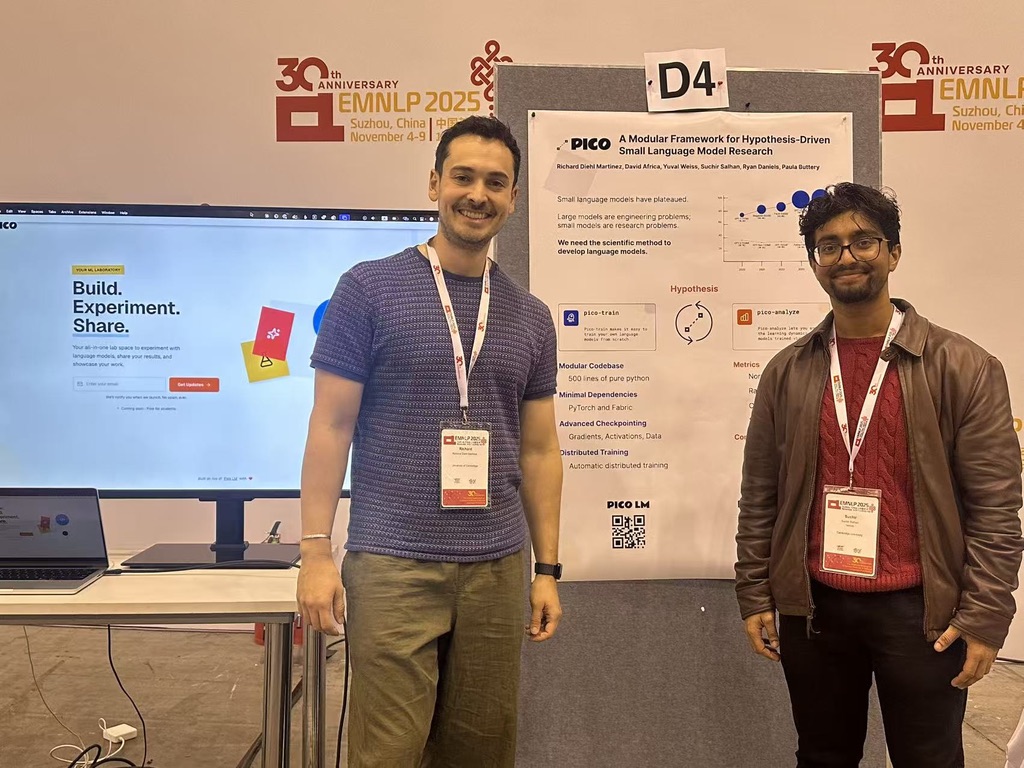
PicoLM poster presentation at EMNLP 2025

PicoLM · Learning-dynamics framework

PicoLM

The problem. Studying how capabilities emerge requires training many small models and inspecting them checkpoint by checkpoint — infrastructure most researchers rebuild from scratch.

What I build. PicoLM is an open framework for pretraining, interpreting and tokenizing small language models, designed for hypothesis-driven experiments on learning dynamics.

Why it matters. It makes small-model research reproducible and comparable, giving a common foundation for the BabyLM community and my own work.

Recent news

Latest

2026
Three main-conference papers accepted at EMNLP 2026 (Budapest) — Beetle, LangMAP and Cross-Lingual Alignment.
Jan 2026
BabyBabelLM accepted to EACL 2026 (Main Conference, Rabat); two oral papers at the 23rd Old-World Conference in Phonology, hosted at Gonville & Caius College.
Sep 2025
Eight accepted papers at EMNLP and NeurIPS workshops, including two Outstanding Paper Awards at BabyLM 2025.
Mar 2025
Released PicoLM, the Cambridge small language model and learning-dynamics framework.

Recognition

Awards

BabyLM Workshop · EMNLP 2025

Two Outstanding Paper Awards

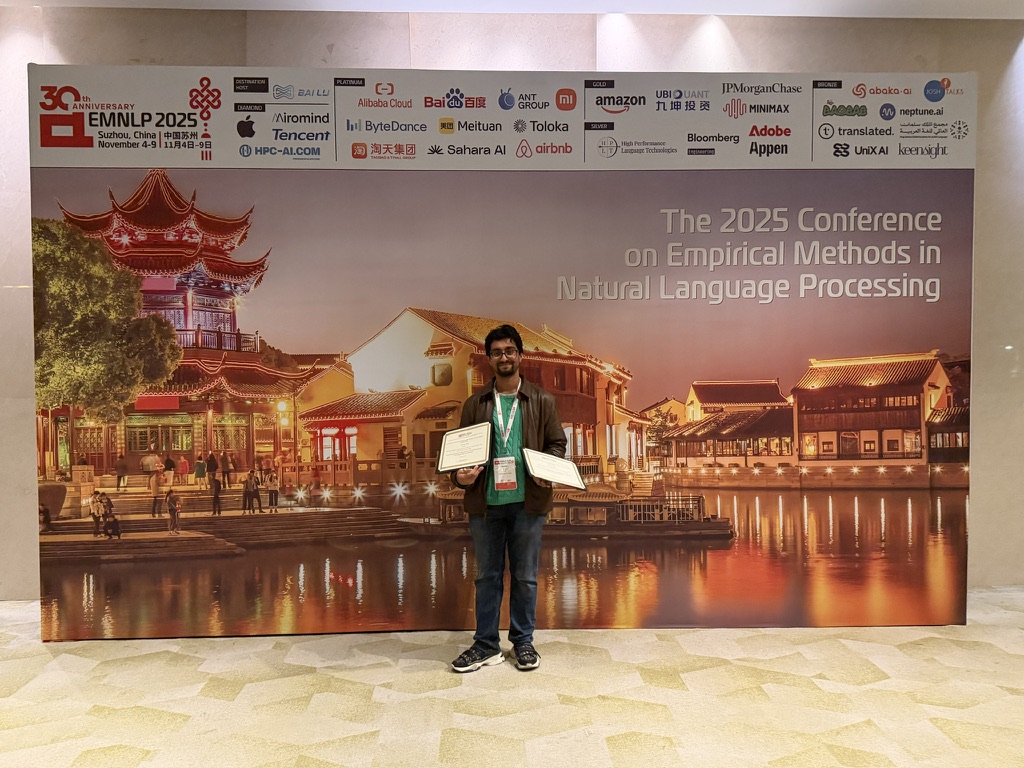
Recognised at the BabyLM Workshop in Suzhou for work on sample-efficient, human-scale language modelling.

EMNLP 2026

Two Oral Paper Awards

Recent work selected for oral presentation at EMNLP 2026.

Invited talks

Presenting human-scale AI research at EMNLP

Working with me

Supervision & collaboration

I am looking for motivated MPhil students interested in developing and understanding language models. Projects are based in the Cambridge Natural Language and Information Processing (NLIP) group, with opportunities to collaborate across Computer Science, Linguistics and Cognitive Science.

  • Real research questions using controlled language models, open-source training infrastructure and interpretability methods
  • Four project areas: dynamic tokenization, sample-efficient AI, developmental interpretability, and bilingual modelling with Beetle
  • Scope to produce publishable work, with possible co-supervision in AI safety, interpretability or computational psycholinguistics

About

Background

Suchir Salhan

I am a PhD candidate in Computer Science at the University of Cambridge (Gonville & Caius College), supervised by Professor Paula Buttery. My research sits at the intersection of machine learning, computational linguistics, cognitive science and AI safety.

I previously completed a BA and MEng in Computer Science and Linguistics at Cambridge, earning a Starred First (Class I with Distinction) and a Distinction. My master's work drew me into the BabyLM Challenge, and from there into the broader question of how models acquire their capabilities.

I co-organise the BabyLM and BabyVLM research challenges, lecture and supervise in Cambridge, and organise the weekly Cambridge NLIP seminars, open to the public.

Read more about me

Get in touch

Say hello

I am always happy to hear from prospective students, collaborators and anyone curious about small language models.

Department of Computer Science & Technology, University of Cambridge · Gonville & Caius College